

dsh-web
zhu1090093659/dsh-webDeepSeek Harness(DSH)Web 插件聚合生态包 · 一切皆插件,创意工坊分发(dsh-market.com)
Canonical project memory for the Pi coding agent. Every asset has at most one governing article, at an address computed from the asset's own path: src/core/config.ts is governed by articles/src/core/config.md. Beneath the articles sits an append-only journal, one file per event. When a tool call touches a governed asset, that article's one dense line arrives in the session unasked, so the agent does not have to know there was something to look up. Detecting the path in a tool call is best effort; resolving it to an article is not.
One setup measured, others welcome. pi-canon was developed and tested under one configuration: Codex, with GPT 5.6 as the worker model, on an OpenAI subscription. Every number in this README was measured there. Other models, other providers, and API-metered access are untested. If you run it under a different setup, feedback is welcome and so are pull requests.
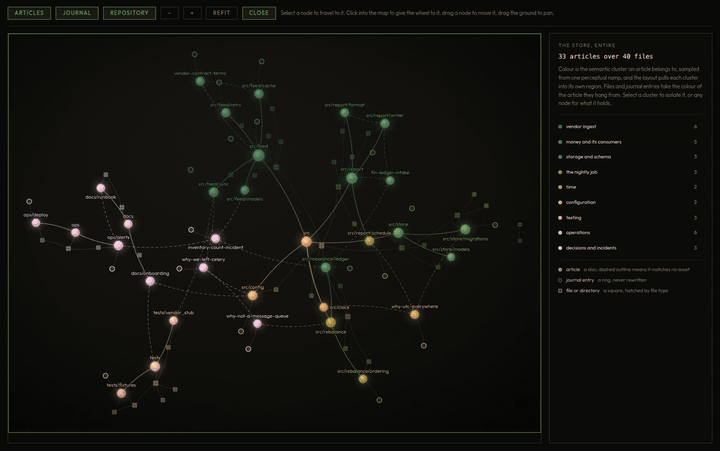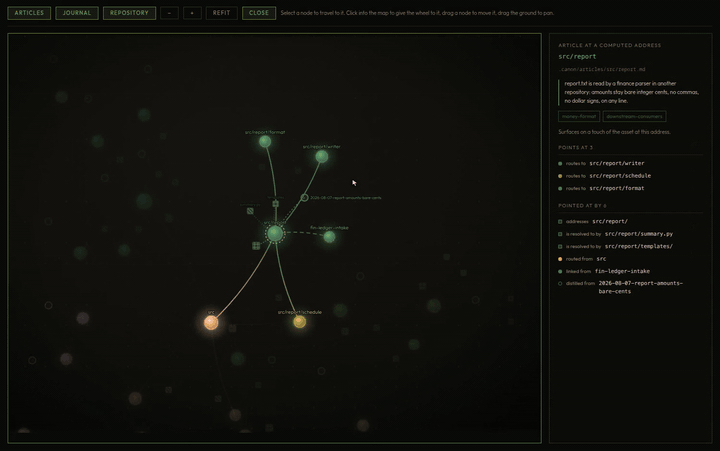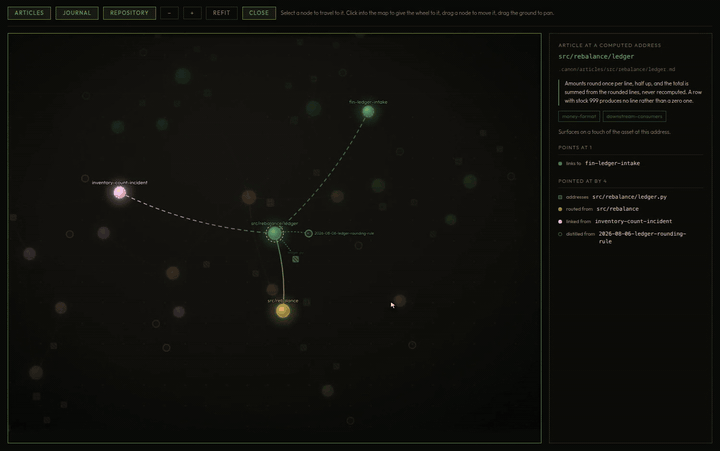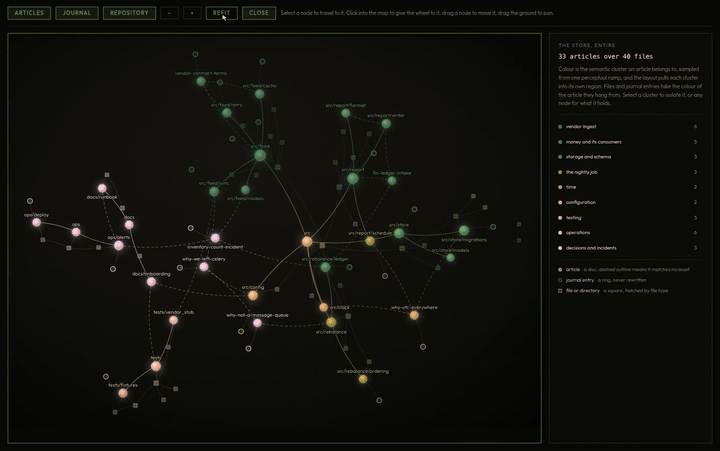
An illustrative store: 33 articles, 20 journal entries, 40 files. Discs are articles, rings are journal entries hanging under the article each was distilled into, and a square tethered beneath a disc is the asset that article was named for. Six of the articles match no asset and hang untethered, because free knowledge is not a special case here. Selecting a node opens what it holds, what it points at, and what points at it.
pi install npm:pi-canon
Or clone this repo into ~/.pi/agent/extensions/. Node 22.18 or later, Pi 0.83 or later on the 0.x line. Nothing to configure: the store is created on first write at <project>/.canon. The package imports node:fs and node:path and nothing else, makes no network calls, runs no git, and loads under plain node with no build step.
The repository is a Codex marketplace. Add it once, then install the plugin at user scope:
codex plugin marketplace add shaneconner/canon
codex plugin add canon@canon
For a local checkout under development, replace shaneconner/canon with its absolute path. Start a new Codex thread after installing or updating it.
The same repository is also a Claude Code marketplace:
claude plugin marketplace add shaneconner/canon --scope user
claude plugin install canon@canon --scope user
Again, an absolute checkout path works for local development. Start a new Claude Code session after installing or updating it.
dsh plugin --profile <name> add dsh-canon
Published separately on npm as dsh-canon, built from the same mirrored core. That build ships without the retriever and without the settings screen.
The Codex and Claude Code plugins launch the same dependency-free MCP server and expose the same canon actions as Pi. Codex surfaces after each tool result. Claude Code deduplicates one capsule packet across each parallel tool batch, immediately before the next model request, which avoids repeated message framing without delaying the agent's next decision. Both give one write-after reminder before the agent stops. An article surfaces at most once per compaction cycle: a compact starts a new cycle, while resuming the same uncompacted session does not. One session may contain several compaction cycles. Compaction discards prior touch state and replays nothing. After it, only a fresh tool-input path can surface that asset's exact or nearest-ancestor article; children and unrelated articles do not ride along. The hooks are inert in projects without .canon/articles, and they never create a store merely because a session opened. Review and approve the plugin hooks when the client asks. Journal entries written through the MCP server carry explicit harness provenance and a session identifier when the client exposes one.
What you have after installing, with nothing configured:
retrieval: "none" is the default because the channel pays only where the store holds knowledge the address spine cannot reach, declared rules governing no asset, and the package cannot know which kind of store it faces. It also needs a retriever this package deliberately does not choose for you. Turn it on with retrieval: "lexical", and the standout gate arrives at its measured default of 1.4 with the drained-store guard.The whole option surface is six keys: root, surface, resurface, retrieval, standout, mounts. Each is documented under Options with the measurement that set its default. Everything else is a constant on purpose.
A session is not greeted: through 0.2.0 every session opened with an orientation line. A 2x2 experiment with an inert implementation found significant negative main effects for both that line and the tool schema, but their 19/32 versus 21/32 comparison did not resolve which component cost more. Study 3 detected no benefit loss when the line was removed, so 0.2.1 deleted it. The tool description carries the doctrine instead. The first article takes one tool call:
{ "action": "write",
  "path": "src/core/config",
  "capsule": "Loads layered config; env beats file; secrets never land here.",
  "body": "Resolution order is defaults, then config.toml, then environment. ..." }
Wrote src/core/config.
The store, after that write and a little later work:
.canon/
  articles/
    src/core/config.md        governs the src/core/config address
    lake/prices.md            articles are not limited to code
  journal/
    2026-08-11-vendor-cap.md  one file per entry, never rewritten by the tool
The article itself:
---
capsule: Loads layered config; env beats file; secrets never land here.
updated: 2026-08-11
---
Resolution order is defaults, then config.toml, then environment. ...
That is the whole storage format. capsule is the one dense line surfacing sends, collapsed to a single line on write whatever the agent sent. updated is the date of the last write that changed something: a write identical to the stored article is a no-op that touches nothing, so the stamp is not refreshed by restatements, and nothing compares it against the asset. Those two keys are the only ones pi-canon owns. Every other key in the block, Obsidian properties included, is carried through writes verbatim, and owned values are quoted only where plain YAML would misread them, so the tree stays editable by hand.
The result is plain Markdown and a valid Obsidian vault. Commit it with your repo: git is the history, diff, blame, and time machine, and pi-canon never runs git itself. Journal entries are ordinary files too. The tool only appends them; read them with normal file tools.
An agent formats a column of raw integer cents for a human reader, 2,255.65 where the file carried 225565. The tests pass. In another repository, one nobody opened during that session, a finance parser reads that file and treats any line with a comma in it as corrupt, so it drops the line and reads on. No exception, no failing build, and a number missing from a downstream total until someone reconciles by hand.
Retrieval cannot prevent this, because a search only runs when something thinks to run it. Formatting a number for readability is not a moment that raises a question. There was nothing to suspect, so there was nothing to search for.
The expensive failures in project work are not the ones where an agent looked something up and got a bad answer. They are the ones where nobody knew there was a question to ask.
That scenario is not a war story. It is one of the five chains in the benchmark below, written because it is the shape of failure this package exists to prevent. No arm of that benchmark is search-driven, so this is the motivation for the design rather than a measured comparison against retrieval.
The shape underneath pi-canon is the LLM wiki: a folder of Markdown articles an agent writes and rewrites, linked to each other, with no schema declared in advance. Andrej Karpathy introduced and popularized the pattern in llm-wiki.md, positioned against re-retrieving raw chunks at query time. Most of what it gets right is kept here unchanged. Plain files, so anything can read them and a person can fix one in an editor. No database and no index to rebuild. Committed with the repository, so git supplies history, diff, and blame. And no schema up front, so knowledge takes the shape the project actually has.
That freedom is also where these stores fail, in two specific directions rather than vaguely.
Scatter. Nothing marks any article as the article about a topic, so an agent that cannot find the existing one writes another. Now there is a note on the vendor feed, a second on feed pagination, and a third on the sync job, all describing the same constraint from three angles, none of them wrong. Retrieval finds all three, the agent reads whichever ranks highest, and when they disagree nothing decides between them.
Log drift. A store an agent writes to during work fills with events, because work is made of events: what was tried, what failed, what got fixed. Current truth ends up under a running log of how it came to be true, and the page that should say what the rule is says what happened on the fourteenth instead.
Neither is a storage failure. In both, the knowledge is present, written down, sitting right there in the folder. Scatter is an addressing failure: precedence is undefined across copies because nothing names one of them canonical. Log drift is a mutability failure: event history and current reference knowledge share one page, and a later rewrite can edit either one out from under the other.
pi-canon is an increment on the pattern rather than a replacement for it, and it adds three things.
A journal, append-only, one file per event. Agents log whether you want them to or not, and that impulse has to land somewhere that is not the reference page. The instruction on the way in is to record the source as it arrived, names and exact numbers included, because articles distill and only the journal keeps the original.
A spine, the addressing convention. An article's address is computed from the asset instead of searched for, and nothing has to be configured for that mapping to hold, which makes the spine a convention rather than a mode. It is also why nothing in the RECALL path searches: when a touch already decided the address, there is nothing to find. The search action exists for the opposite direction, the agent that wants to ask, and it never runs unasked.
Surfacing, push rather than pull. When a tool call is detected touching a governed asset, that article's capsule is staged for the session, at most once per article while it stays in context (see Surfacing), so nobody has to think to ask. Detection of a path inside a tool call is best effort. Resolution, once a path is in hand, is not.
The evaluation below does not test that lineage argument: no evaluated arm is a search-driven LLM wiki, so nothing here shows pi-canon beats a disciplined one.
The address is the asset path with its file extension dropped, and the drop happens once, at the boundary. A name has to precede the dot, so .env stays .env. Only a dot after the last slash counts, so docs/v1.2/notes.md normalizes to docs/v1.2/notes. And src/core/config.test.ts lands at src/core/config.test, beside config rather than on top of it. Dot segments clamp at the root, and containment is checked a second time inside write, so no address escapes articles/.
Resolution tries the exact address, then walks up one path segment at a time to the nearest existing article, and returns nothing if it reaches the top without a hit. There is no ranking, no scoring, and no similarity: given a path, the governing article is a function of what exists in the tree. So not every file needs an article: one article at src/feed answers for everything beneath it that has no closer article. Creating an article is the uncommon act; the common one is updating the article that already governs.
A rename is a file move you make yourself. pi-canon does not watch the filesystem and has no rename action. Move the article to the address the new path derives. Lint checks the wikilinks inside whatever article is written next, so a link left pointing at the old address is named the next time that article is written, not at the moment of the move.
An article matching no asset is ordinary free knowledge. The spine guarantees an address for the assets a project already has; it does not confine the store to them. The tradeoff is worth stating in the same breath: surfacing is asset-scoped, so an off-spine article is reached by a link or an explicit read rather than pushed on a touch, or by relevance when a retriever is configured.
Such an article may say so, with scope: rule on the write. Forgetting the declaration never excludes an off-spine article from retrieval. Declaring it separates a rule filed on purpose from an article whose asset disappeared, and keeps that rule in the retrieval corpus if an asset later appears at the same address. scope: asset takes the declaration back.
One tool, canon, five actions: read, write, journal, map, and search.
| action | parameters | does |
|---|---|---|
read | path | Returns the governing article: title, capsule, updated, body, and a one-line journal index. A miss returns a sentence naming the address and inviting a write after the task. When an ancestor answers, the title reads <ancestor> governs <address>, so the altitude is visible. |
write | path, capsule, body, scope | Creates or updates the article, then returns Wrote <address>. and any advisory lint. Never refuses. An empty string means untouched, not erase. A write identical to the stored article is reported as already current and touches nothing, so updated keeps meaning the date the content last changed. |
journal | body, subject, slug | Appends a dated entry as its own file, <date>-<slug>[-n].md. canon can never rewrite one. An empty body gets a sentence back asking what happened. |
map | path (optional prefix) | One line per article as address: capsule, or a sentence when the store or the filter is empty. Output is unbounded. |
search | query, journal | Ranks articles against the words, ten results, each carrying what scopes it: an article its address and capsule. The journal is opt-in via journal: true, because events are history rather than current truth, and measured on real stores journal entries about an event crowd out the article carrying it; a default search never reads an entry body and says the journal exists. Opted in, journal entries are first class results scoped by instant and subjects, articles keep half the window, and a short side cedes its slots. Says how many matches the cap dropped. The one action that reaches the journal's content. |
subject is an array of addresses. A subject passed as a bare string is ignored and the entry lands with none at all.
Entries logged with subject addresses come back as a one-line index of filenames, newest three, when those articles are read: history on offer, never loaded by default. The index carries filenames only and never entry content, and matching is exact, so an entry filed at src/core/config does not appear when src/core is read. The journal always lives in the project store.
Lint on a write is advisory strings appended to the response, never a refusal, because a blocked write teaches an agent to stop writing while a warning teaches it what to do next. The one exception is a rule the store itself declared required in its schema, documented in The article schema below. It warns past 8,000 characters of body and suggests going hierarchical past 20,000. It names a missing capsule, one over 1,000 characters, or one written as a change log. An address carrying a log, journal, session, standup or meeting segment, or an ISO date, draws a redirect to the journal. Dead wikilinks are named one line each. An article whose asset went missing is named on read and on write: a nested address whose parent directory exists on disk while nothing matches the asset draws the orphan question, with the ways out spelled (move the article, fold it into the parent, or declare scope: rule). Root-level addresses, declared rules, and stores whose addresses never mapped to files stay silent.
A rewrite that grows the body says so in its own result: Body grew 812 -> 1304 bytes., followed by the reminder that an article carries current state and narrated history (old values, transitions) belongs in the journal. Any growth fires; creation is not growth, and a capsule-only write never grows the stored body. This line is measured, and the measurement is a direction rather than a size. Across three two-arm captures over byte-identical eight-session lineages, the arm whose tool spoke it ended with fewer superseded values standing every time: 51 against 88 of 96 on one model, 45 against 87 on a second, and 71 against 85 when the first model was run again with the arm order reversed in half the lineages. Take the direction and not the magnitude. That third capture kept the direction and lost most of the gap, and re-running a matched untreated cell two days later moved its median store 39 percent, so the instrument does not measure its own magnitudes reliably. Store size never carried either: it fell a fifth, then barely moved, then fell two fifths, and across the paired lineages the direction of that change is not distinguishable from chance in the first two captures. Two readers out of 96 were harmed by a stale value, one from each arm, so the line is not known to protect readers. The same doctrine in a system prompt cleared one superseded value in thirty-two, though that arm ran in a separate one-session study and the two were never placed side by side.
One lint line is different in kind. When a write supplies a body and an article was already there, the new body is compared against the prior one, and a line that carried constraint language and disappeared is quoted back at the write that removed it. The vocabulary is fixed: must, never, always, require in its requires and required forms, do not, and don't. At most two lines are named per write, each cut to its first 160 characters, with the note that if the constraint still holds it should stay, and if it genuinely changed, the change belongs in the journal. The quote is a prefix rather than a summary. It is an advisory: the write already landed, and nothing can make an agent put the line back.
Every store carries its contract as a file: schema.json at the store root, written with the shipped defaults made explicit the first time the store persists anything. It is data rather than configuration, so it travels with the store, differs per project, and any other tool reading the store can enforce the same contract from the same file. The shipped defaults require nothing and mirror the advisory caps, so an untouched file changes no behavior; it only makes the contract visible and editable.
Three fields can carry rules: capsule (the front matter line surfacing injects), title (the body's leading # heading; there is deliberately no separate title input, so the rule checks the one place a title can live), and body. Four rule keys: required, min_chars, max_chars, hint.
Enforcement is asymmetric on purpose, and the asymmetry is measured: across five write-quality model captures in this project's lab, rules held at the tool boundary erred at zero while rules left to model judgment erred at about one percent. So the class of miss that matters is enforced rather than advised:
required rejects the write that violates it, hint included, and nothing touches disk. A write is judged on what it changes, plus everything when the article is first created, so a capsule-only update is never held hostage to a legacy body.schema.json fails open and loud: rules stop being enforced and every write says so, because a contract the owner believes is enforced while a typo disabled it is the worst state.A store that requires every article to open with a heading:
{
  "schema_version": 1,
  "article": {
    "capsule": { "required": true, "max_chars": 1000, "hint": "One dense line of current truth." },
    "title": { "required": true, "hint": "Start the body with a # heading naming the asset." }
  }
}
Delete a rule to drop it; delete the file to disable schema checks entirely. An edited file is never overwritten.
Relations rules live in the same file under relations, because the reference graph is part of the contract too; each tool enforces the rules it can see, so one file governs every tool that reads the store. This package sees an article's own citations at the write boundary and enforces refs: required rejects a write whose body cites nothing, judged like the field rules (the write that changed the reference set, or a creation), and min_count warns under a floor, with code-fenced examples and case-folded duplicates never counted. The two graph-wide rules parse here and are enforced by graph-reading tools such as canon-atlas: orphan.warn warns when no other article references this one, and children.listed warns when an article does not reference each direct child under its address.
{
  "schema_version": 1,
  "relations": {
    "refs": { "required": true, "hint": "Name what this concerns." },
    "orphan": { "warn": true },
    "children": { "listed": true }
  }
}
A tool call stages the governing article for whatever it touched and sends nothing. Each turn end flushes everything staged as a single message, because pi's steering queue drains one message per provider round trip and a message per tool call would buy every nudge its own model call. An article with a presence mark surfaces at most once while that mark remains in the context the provider receives; one folded or compact
DeepSeek Harness(DSH)Web 插件聚合生态包 · 一切皆插件,创意工坊分发(dsh-market.com)
把回答做成一页可视化 HTML:模型只写简短的 Markdown 草稿,随包附带的 `am` 命令行生成页面,支持流程图、时序图、树、时间线、ER 图、表格和提示框。
在 dsh 里装上这个插件即可,无需登录、注册或填 API Key,就能使用包括 Muse Spark 1.3、MiMo V2.6 在内的前沿模型——完全免费,不限量。 All you do is install this plugin in dsh: no login, no sign-up, no API key — the frontier models are just there, Muse Spark 1.3 and MiMo V2.6 among them. Completely free, with no usage cap.

