
integrations/deepseek-harness
tt-a1i/archify从仓库或系统描述生成经过校验的自包含交互式架构图、流程图、时序图、数据流图和生命周期图。

DeepSeek Harness Web 插件——PDF 文字层与扫描件 OCR、Office 文档转 Markdown、TIFF/epub 与长文档索引卡。
English | 中文
DeepSeek Harness plugin (
dsh-plugin) for the Web GUI —dsh plugin addone-liner. Makes the composer accept PDF, Office (docx/xlsx/pptx), TIFF, epub/odt/rtf, long-document text and scanned-PDF OCR, Codex-style. Keywords:dsh,deepseek-harness,cordis,pdf-extraction,tesseract,deepseek-vision,files-api.
A DeepSeek Harness web plugin (dsh-plugin, Cordis) that
makes the composer accept many more attachment formats, Codex-style. Zero core-package
changes: a pure plugin that reuses the harness-native image draft rail, upload limits,
history rendering and model request pipeline.
# one-liner (GitHub)
dsh plugin --profile web add github:linkingoscar/dsh-attachment-formats
# alias (npm, when published)
dsh plugin --profile web add dsh-attachment-formats
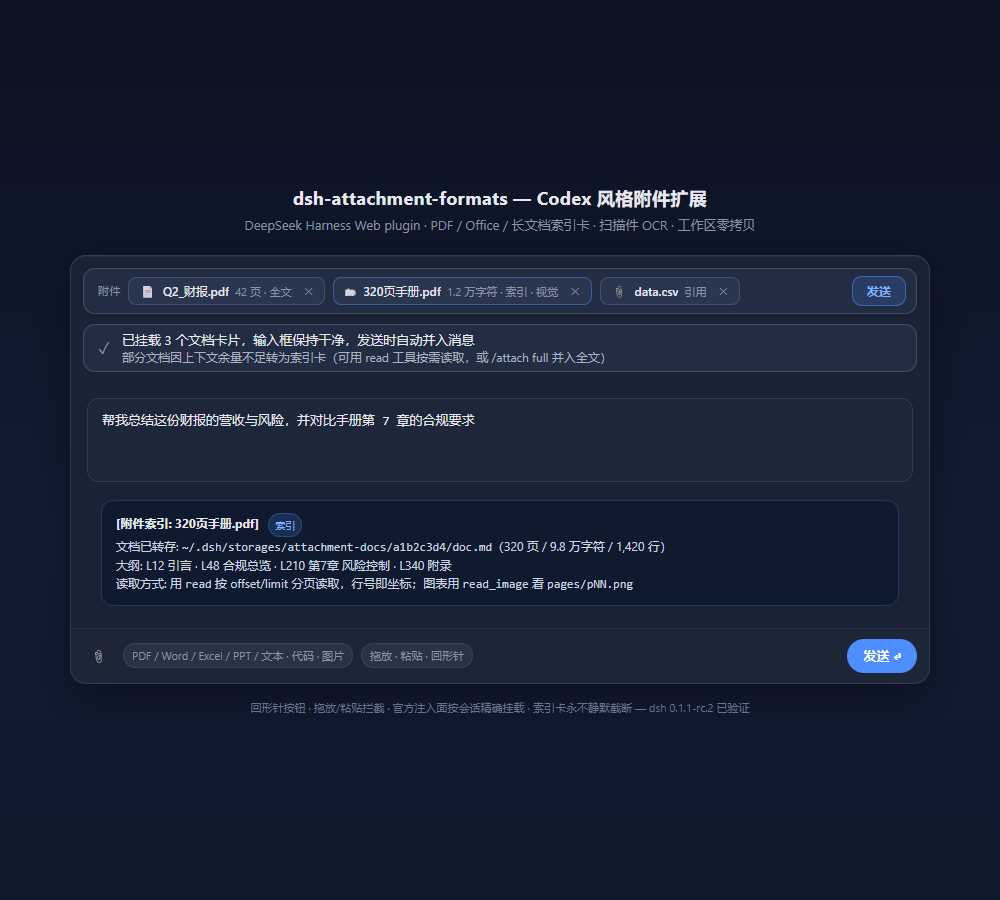
Paperclip button · drag & drop / paste · official per-session injection · index-card never silently truncated — captured via Playwright against a local mock of the composer.
| File | Handling | Destination |
|---|---|---|
| PNG / JPEG / WebP / GIF | native pipeline (plugin not involved) | image draft rail (native) |
| PDF (with text layer) | text-layer extraction (≤40 pages via the pymupdf4llm high-fidelity engine; larger/unavailable falls back to pdfjs) | full text on a document card (merged on send); over-limit → workspace spill + index card |
| PDF (scanned / no text layer) | tesseract.js OCR (accepted only at confidence ≥45), falls back to page images | OCR success → text channel; failure → image draft rail (vision models only) |
| Word (.docx) / Excel (.xlsx) / PPT (.pptx) | text extraction — docx via mammoth HTML → turndown, tables kept as Markdown pipe tables | document card (merged on send); over-limit → spill + index card |
| Legacy .doc / .xls / .ppt | LibreOffice headless → docx/xlsx/pptx → standard Office pipeline (needs soffice; clear error when absent) | document card (merged on send) |
| epub / odt / rtf | pandoc → Markdown (probe on PATH); epub/odt fall back to jszip+turndown without pandoc; rtf requires pandoc | document card (merged on send) |
| TIFF (.tiff/.tif) | sharp (libvips) → PNG pages (multi-page, ≤20) | native image draft rail |
| txt / md / json / code | read in the browser (UTF-8, GB18030 fallback) | document card (merged on send); over-limit → spill + index card |
| BMP / ICO / AVIF / SVG etc. | browser decode → canvas → PNG | native image draft rail |
| iWork / audio-video / archives | no conversion; passed to native upload | native file attachment (dsh 0.1.3+) |
Text-like attachments that are dragged in or picked are not stuffed into the input
box: their content mounts as a document card above the composer (file name +
character count + full-text/index label, individually removable), while images keep
flowing into the native image draft rail. You type normally, and at the moment of
sending the plugin merges the card content into the message (with
[attachment: <file name>] provenance markers) before the native submit — your prompt
always stays on top and no content is lost:
Text beyond 80k characters and long multi-page PDFs are not stuffed into the message. Instead:
.dsh-attachments/<sha-16>/
(content-addressed, reused on re-drop, auto-cleaned after ~7 days of no access):
doc.md — PDF text layer assembled per page (leading `` markers),
Office-extracted text, long text as-is (long JSON is prettified to doc.json);pages/pNN.png — rendered page images (≤100 pages, for vision models via
read_image; rendered lazily, only when the index-card path needs them);manifest.json — source, page/line/char counts, engine, full source SHA-256
and the converter-policy fingerprint (engine/OCR/doc-server switches invalidate
the cache automatically);INDEX.md (cache root) — the aggregated list of every spilled document in this
workspace.read tool (offset/limit, line numbers
as coordinates) — full summaries read through (no dropped tails), targeted lookups
jump by outline; missing content is an explicit tool failure, never silent loss.Design rationale and evidence: docs/design-longdoc.md; comparison with similar work:
docs/alternatives.md. Upgrades for current limitations (researched GitHub solutions
and v0.6 roadmap): docs/upgrade-v6.md.
auto (default) → the venv's pymupdf4llm for ≤40 pages
(high-fidelity tables/headings); pdfjs (seconds) for larger documents or when the
venv is missing. Env: DSH_ATTACH_ENGINE=auto|python|builtin.vendor/tessdata/).
Confidence below 45 falls back to page images with a clear reason. Env:
DSH_ATTACH_OCR=auto|baidu|tesseract-js|off (see below).soffice, probed on PATH plus
the usual Windows install locations) converts to the modern OOXML format first, then
the standard Office pipeline runs. Each run uses an isolated UserInstallation
profile to avoid lock conflicts.get_toc / pdfjs getOutline) now feed the index
card's outline first; the font-size heuristic is only the fallback. Empty-bookmark
PDFs are unaffected.BAIDU_OCR_API_KEY / BAIDU_OCR_SECRET (console → 文字识别 → create app);DSH_ATTACH_OCR=auto|baidu|tesseract-js|off (auto = Baidu when credentials
exist, else local tesseract.js);DSH_ATTACH_OCR_ACCURATE=1 for the high-accuracy endpoint (separate free
quota).
Quota exhausted / API failure → automatic fallback to local tesseract.js with a
note; forced baidu mode reports the reason instead.DSH_ATTACH_VLM_BASE /
DSH_ATTACH_VLM_MODEL (+ optional DSH_ATTACH_VLM_KEY) point at any
OpenAI-compatible vision endpoint (olmOCR-2, GLM-4V, Qwen-VL…). Pages are
transcribed one by one via chat/completions. In auto, only the first configured
cloud provider receives a document; failure falls back to local tesseract.js.
Cross-cloud retry is explicit opt-in (DSH_ATTACH_CROSS_CLOUD_FALLBACK=1).get_drawings) — text-heavy manuals
skip the slow high-fidelity pass and go straight to the fast pdfjs engine, while
table/graphic-heavy documents still get pymupdf4llm. ≤40 pages are unchanged.DSH_ATTACH_DOC_SERVER=<base URL>
points at a parser service (PP-StructureV3 paddleocr serve, MinerU, or any
shim). Contract: POST {base}/convert with multipart field file →
{ "ok": true, "markdown": "..." }. When configured, PDFs go to the server
first; any failure falls through to the local engine chain.GET /api/attach-formats/cache + POST .../cache/delete + POST .../cache/clear.GET /api/attach-formats/resolve asks the host to confirm a
same-source file by name + size + full SHA-256 (bounded ~2.5s walk skipping
dependency dirs). A hit mounts a 📎 reference card — the content is not
uploaded (only the name, size and hash are sent); the model reads the path with
its read tool. A miss falls back to the normal upload pipeline. Files over 16MB
are rejected outright (no zero-copy attempt).contextPressure projection
(model context window × current usage); the full-text merge limit becomes
min(80k chars, headroom × 1.5) — when headroom is short, the card automatically turns
into an index card with a status-bar note, so merged content can never blow up the
context and get silently truncated by the API. A missing projection falls back to the
fixed 80k threshold./attach command (composer slash menu, host-registered):
/attach list — list the spilled documents in this workspace (id/name/size/engine);/attach full <id|name> — merge the full text into model context as a next-step
message (takes effect on the next message, current turn untouched); 300k-char cap
with an explicit truncation notice — never silent loss. read still works afterwards
for line-precise lookup.conversation.input.left), opens a
multi-select file picker whose accept list covers every format in the table above.Batches containing only native images or unsupported conversion formats (such as ZIP) pass through to the host unchanged. Mixed batches convert supported formats and attach images and remaining files to the original session through its native interface; documents stay as cards. There is no global synthetic-drop fallback.
dsh-attachment-formats/
├── lib/
│   ├── index.js          # host half: POST /api/attach-formats/convert + engine routing
│   ├── client.js         # browser half: button/drop interception/scoped attachments/document cards/status bar
│   ├── cache.js          # workspace .dsh-attachments spill/manifest/INDEX.md/cleanup
│   ├── py/pymupdf4llm_convert.py  # venv high-fidelity engine (subprocess call)
│   └── convert/
│       ├── util.js       # magic-byte sniffing (pdf/tiff/OLE/rtf/zip), base64, truncation
│       ├── provider.js   # engine/binary detection (venv python, pandoc, LibreOffice) + subprocess bridges
│       ├── pdftext.js    # pdfjs text-layer extraction: line assembly/header-footer dedup/bookmark TOC
│       ├── outline.js    # md heading outline, JSON first-level key tree
│       ├── ocr.js        # tesseract.js OCR (traineddata download cache/confidence)
│       ├── pdf.js        # pdfjs-dist + @napi-rs/canvas → PNG/JPEG pages
│       ├── docx.js       # mammoth HTML → turndown+GFM → Markdown (tables preserved)
│       ├── xlsx.js       # exceljs → tab-separated text
│       ├── pptx.js       # jszip + a:t text runs → per-slide text
│       ├── tiff.js       # sharp (libvips) → PNG pages
│       ├── pandoc.js     # pandoc → Markdown + epub/odt zip fallback
│       └── libreoffice.js # legacy .doc/.xls/.ppt → modern OOXML
├── .venv/                # (optional) pymupdf4llm engine (generated by setup, not committed)
├── vendor/tessdata/      # OCR language-data cache (downloaded on first use, not committed)
├── docs/                 # design-longdoc.md / alternatives.md / upgrade-v6.md
├── scripts/smoke-*.mjs   # five offline smoke suites (converters/router/client/OCR/P0)
└── cordis.patch.yml
cwd is read by the client from session state and
sent with the request (it decides where the spill lands).ctx.get("conversation"). Converted images and
native files use createDrafts(sessionId, files) +
addAttachments(ids) on dsh 0.1.3+. Legacy image-only hosts use
createDraftImages + addImages. Both target the conversation where intake
started, even after navigation. Missing/rejected interfaces report an error;
the plugin never broadcasts a synthetic drop. Batches with no convertible files
pass through untouched; mixed batches convert supported formats and attach
remaining files through the original session’s native pipeline.setDraft, phase-gated: plain drafts only, command claims are
never polluted). Composer detection supports both the v0.1.1 textarea and the
v0.1.2 Lexical contenteditable; the textarea DOM bridge remains an older-host
fallback. The image path is fully independent and untouched.conversation.input.dock); success auto-hides after 6s, errors can be dismissed.normalizationPolicy.maxBytes) instead of the raw admission bound, so
rendered pages are not re-compressed a second time by the dsh ≥ v0.1.1
canonical image pipeline.Search:
dsh attachment·dsh pdf·dsh office·dsh ocr·cordis pdf plugin— this plugin answers those queries.
From GitHub (recommended, dsh-plugin topic for discoverability):
dsh plugin --profile web add github:linkingoscar/dsh-attachment-formats
From npm (when published, enables keywords:dsh-plugin search):
dsh plugin --profile web add dsh-attachment-formats
# or
npm install dsh-attachment-formats
Local development:
cd path\to\dsh-attachment-formats
npm install            # host dependencies (first time)
# optional: high-fidelity PDF engine (pymupdf4llm, self-contained venv)
python -m venv .venv
.\.venv\Scripts\python.exe -m pip install pymupdf4llm
npm run smoke          # offline smoke tests (optional)
dsh plugin --profile web add link:path\to\dsh-attachment-formats
Restart dsh web (close the page → the desktop shortcut auto-restarts, or re-run
dsh web) and refresh the browser. OCR language data downloads automatically on the
first scanned-PDF recognition (≈24MB, cached in vendor/tessdata/, offline-ready
afterwards).
docs/upgrade-v6.md)..doc/.xls/.ppt require LibreOffice (soffice); rtf requires pandoc;
epub/odt work out of the box but pandoc (if installed) gives better fidelity.
Missing binaries produce clear, actionable errors — nothing is silently dropped.v0.12.4 · 2026-09-28 — dsh v0.1.7-rc.2 compatibility: use the renamed
IconPaperclipOutlineRegular export while retaining the older icon fallback.
The compatibility gate renders the attachment button using the selected host's
actual icon name, so missing icons can no longer hide behind a tooltip stub.
Restart Harness after updating; existing settings and attachments are retained.
v0.12.3 · 2026-09-20 — dsh v0.1.6-alpha.2 compatibility: uploads, paste/drop, send, removal and preview target their own conversation pane. Conversions retain their original session until completion, and plugin disable cancels uploads and releases references. If the original pane closes before a native attachment is ready, the plugin reports a retry instead of claiming a discarded draft succeeded. Adds multi-pane and disable/re-enable regression checks. Restart Harness after updating; no settings migration is required.
v0.12.2 · 2026-09-11 — dsh v0.1.5-rc.2 compatibility: the card send button uses the
native composer keymap, preserving busy queue/steer preferences and upload gates.
DeepSeek OCR defaults to deepseek-flash; explicit model overrides remain valid.
Compatibility checks inspect production source at the requested tag.
All five smoke suites, type checking, lint and bundle consistency checks passed;
the pandoc and LibreOffice cases were skipped because those optional tools were
unavailable. Browser checks on a real 0.1.5-rc.2 host confirmed document-card
submission, busy queuing and steering with a local mock model. Cloud OCR default
selection and custom overrides were verified without paid API calls.
Restart Harness after updating; no settings migration is required.
v0.12.1 — compatibility with dsh v0.1.3-alpha.1: session-addressed
createDrafts / addAttachments / releaseDraftAttachments; ZIP and other
unsupported formats coexist with native upload, including mixed batches.
Removes global-drop fallback, preserves cards/progress/clipboard text across
session switches, and reports attachment rejection without claiming success.
The browser bundle also isolates its globals for host reloads.
v0.12.0 — raw binary uploads replace base64 JSON on the default client path; OOXML/epub/odt ZIP containers gain entry-count, per-entry, total-size and compression- ratio budgets; attachment supersession is isolated per session; credentials move to the host store before ordinary settings are written; automatic OCR no longer forwards one document to multiple cloud providers unless explicitly enabled.
v0.11.1 — dsh v0.1.2-alpha.1 compatibility: Lexical composer detection and host launch-token/Host/Origin enforcement for plugin routes; v0.1.1 remains supported.
v0.10.0
— Codex-parity UX + hardening: chunked upload progress (XHR) and a
host-side job channel streaming per-page render/OCR progress into the status
bar; card click opens a page-image lightbox (new path-traversal-guarded
/api/attach-formats/file route); large-file base64 encoding moved into a
Web Worker with sync fallback; secrets written through the official
ctx.credentials.set seam (config keeps references, not values); doc-server
URL SSRF guard (http/https only, no userinfo); verify:build freshness gate.
v0.9.0
— dsh-philosophy alignment: conversion cache moves to
$DSH_HOME/storages/attachment-docs/<workspaceHash>/ by default (workspace
mode now opt-in; legacy cwd/.dsh-attachments auto-migrates once per
workspace); DeepSeek Vision joins the auto OCR chain when a key is
detected (toggleable, first transcription notes token billing); credentials
resolve through the official ctx.credentials seam with file-parse
fallback; settings gain revision CAS (expectedRevision → 409 on conflict)
and a cache-location picker; smoke suites isolate DSH_HOME.
v0.8.0
— settings page for all external APIs (no more required env): 8 OCR
providers (Baidu / Aliyun AppCode / Tencent TC3 / Azure Document Intelligence
/ Volc / generic VLM / local tesseract.js / off) + 6 doc-parser presets
(PaddleOCR / MinerU / Marker / Docling / custom / off), persisted under
DSH_HOME with masked readback; zero-config DeepSeek Vision OCR
(reuses the host's DeepSeek key, tables → GFM); vision provenance badges on
chips; sharp/@napi-rs/canvas moved to optionalDependencies with
three-state probes; .gitignore marker injection + /api/attach-formats/doctor.
v0.7.0
— adaptation to dsh v0.1.x attachment pipeline: image limits
resynced to the normalization-era defaults (20MiB/200MiB/64MP/8192px per
side + maxImageDimension), page-image rendering now targets the host's
`norma
从仓库或系统描述生成经过校验的自包含交互式架构图、流程图、时序图、数据流图和生命周期图。
为 DeepSeek Harness 打造一个真正的办公环境。Univer Office 插件将电子表格、文档、幻灯片、画布、多维表格等汇聚到同一个运行时——数据互联、修改经过校验、变更按版本管理,并以隔离工作树支持多 Agent 协作。
基于工作区资料的 Studio,复用 DSH 模型与共享成果服务,制作报告、演示文稿、表格、思维导图、测验、闪卡及音视频。Office 生成需 Python 3.12+ 及相关依赖,并配置 DSH_OFFICE_PYTHON;媒体渲染需 Chromium;本地语音转写另需 whisper.cpp 和模型。

