
dsh-web
zhu1090093659/dsh-webDeepSeek Harness(DSH)Web 插件聚合生态包 · 一切皆插件,创意工坊分发(dsh-market.com)

DeepSeek Harness plugin: stops the sandbox escalation fields being advertised to a model when the calling session cannot grant them, fixing the retry loop known models fall into at danger-full-access.
A DeepSeek Harness plugin that stops the sandbox-escalation fields being offered to a model when the calling session cannot grant them.
It fixes a GPT-specific failure. GPT-family models complete every optional
property in a tool's schema, and the two optional properties on bash, write
and edit are exactly the two a full-access session can never use. So GPT fills
them in on every call, every call is rejected before it runs, and the error text
never says that the fix is to omit them. The turn dies with nothing executed.
A model that sends only what a call needs never sees this — which is why it looks like "GPT is broken" while other models are fine in the same session. The fix is not a better prompt: it is to stop publishing fields that cannot be filled. See why this presents as GPT-specific.
The DSH escalation fields — sandbox_permissions and justification — are
advertised from a load-time capability fact but judged at execution against
a per-session policy fact:
| Source | Question answered | |
|---|---|---|
| Advertisement | ctx.shell.sandboxMode | Is a confining executor mounted? |
| Execution | ctx.sandboxPolicy.resolve().mode | What mode is this session actually in? |
They disagree in exactly the case that hurts: a session sitting at the ceiling.
A session whose effective mode is danger-full-access is handed:
"sandbox_permissions": {
  "type": "string",
  "enum": ["workspace-write", "danger-full-access"]
}
Both values are unusable. workspace-write is a reduction, and
danger-full-access is the mode already in force — and the check is
strictly wider, so neither can ever be granted. The system prompt
simultaneously instructs the model to use that field to "escalate immediately".
A model that fills in every optional property it is shown — the GPT family does this — then cannot succeed and cannot tell why:
Error: invalid justification: expected a non-empty sentence
Error: sandbox escalation to "danger-full-access" is not strictly wider than this call's current "danger-full-access" mode
Error: sandbox escalation to "workspace-write" is not strictly wider than this call's current "danger-full-access" mode
Neither text names the only actual repair, which is to omit both fields. The observed result is the same command retried until the turn dies.
Nothing here is model-specific in the harness. The difference is a habit, and it collides with this defect perfectly:
GPT-family models populate every optional property in a tool's schema. Given
command (required) plus sandbox_permissions and justification (optional),
they do not send the minimum the call needs — they send a fully-formed instance
of the schema they were shown. Asked for one string, they fill in three.
That habit is usually harmless. Here it is fatal, because the two optional properties are the exact two that a full-access session can never use. So the model helpfully completes them on every call, each call is rejected before anything runs, and the error text points at the justification field rather than at the real instruction, which is to leave the fields out. Retrying with the same habit produces the same rejection. The turn ends with no command executed and no usable signal about why.
A model that only sends what the call needs never touches those fields and never sees the bug. From the outside, that looks like one model being broken — same session, same harness, same repository, different models, only one of them failing.
The fix follows directly from the diagnosis: if the model completes whatever it is shown, stop showing it things it cannot use. Once both fields are gone from the schema, there is nothing left for the habit to complete, and the failure mode disappears for the model that was most prone to it — without the model needing to know it existed, and without a prompt telling it to be careful, which is the kind of instruction a schema-completing model is least likely to reliably follow.
This is why the primary fix is suppression rather than a clearer error message.
A better message asks the model to behave differently; removing the field does
not depend on the model's cooperation at all. The tools/pre-execute
correction exists only for the residual case — a cached schema, or a model that
ignores the schema it was given.
From one live session (effective mode danger-full-access, approval policy
never), comparing a model that completes optional properties against one that
does not:
| model | tool calls | emitted sandbox_permissions | bash calls | bash + optional field |
|---|---|---|---|---|
zai/glm-5.3 | 211 | 0 | 86 | 48 |
oauth-codex/gpt-6-astra | 10 | 8 | 8 | 8 |
The GLM column is not "a model that tried and succeeded" — it emitted the field zero times in 211 calls. It never entered the failure mode, because it sends only the properties a call needs. The GPT column emitted it on every bash call and lost all eight to the same rejection.
Same session, same schema, same repository, same effective mode. The only variable is whether the model completes the optional properties it was shown — which is why this reads from the outside as "GPT is broken" rather than as a schema defect that one model's habits expose.
Confirmed at the wire level too: the request/header event for that session
shows bash, write and edit each advertising sandbox_permissions with
enum: ["workspace-write","danger-full-access"], so the field was genuinely
published to the model rather than being something it invented.
The tool set is still mutable at system-prompt/assemble, which is a
sanctioned extension point and runs per request. The rewrite is decided by a
session fact — whether an escalation could be approved at all — never by the
current access level:
never, and for any unrecognised mode,
remove both fields entirely and strip the escalation paragraph from the
tool description that would otherwise keep urging the model to use them;An earlier revision instead kept only the enum values strictly wider than the current mode. That is gone, for two reasons:
It moved the cached prefix. The tools block is the front of the cache, so rewriting it on an access-level change discarded the entire cached conversation behind it.
The access level does not move on its own. The shipped permission presets bundle the two knobs, and switching one writes both:
| preset | sandbox | approval |
|---|---|---|
read-only | read-only | ask |
workspace-write | workspace-write | ask |
danger-full-access | danger-full-access | never |
So the access level never changes while the policy stays put. The policy is therefore the key that is constant for the whole life of a preset, which is exactly the lifetime over which the cached prefix must survive.
Because the deciding fact is the approval policy rather than the mode, the
published surface is byte-identical on every request and does not move when the
access level is changed in place. That is the property that protects the cache,
and test/mount.test.mjs and test/real-services.test.mjs pin it directly.
There is no coverage lost in any shipped preset, which is worth stating because an earlier version of this file implied otherwise:
| preset | what the model is offered | correct? |
|---|---|---|
read-only | ["workspace-write", "danger-full-access"] | yes — both are genuinely grantable |
workspace-write | ["workspace-write", "danger-full-access"] | danger-full-access is grantable; workspace-write is the downward direction, and escalation only ever goes wider |
danger-full-access | (fields removed) | yes — nothing is wider, so every value would be rejected. This is the reported failure. |
Escalation is strictly widening, so a model never asks to narrow itself. The surface above is consequently the correct one for every preset the harness ships.
It still judges grantability by the same strictly-wider ladder
@deepseek-ai/dsh-sandbox exports and approveEscalation enforces, so the two
cannot disagree about what is grantable. That ladder is mirrored in
lib/wider-modes.js rather than imported, which is why this package has no
runtime dependency — it plugs into the host contract alone (apply +
inject). A test/wider-modes.test.mjs drift guard compares the mirror against
the harness's own export and fails if DSH ever changes the ladder.
For a session under a never policy the model now receives a bash tool with only
command and description, and no escalation prose at all — in every mode.
A client holding a cached schema, or a model that ignores its schema, can still
send an unusable request. tools/pre-execute then denies it with text that
names the effective mode, states that no value is grantable, and names the
repair — instead of the two opaque validations.
This is a fallback where (1) applies, and the only mechanism where it does not.
In a session under an ask policy the surface is deliberately left intact, so
this listener is what keeps an unusable call from failing opaquely.
It only stops offering modes that cannot be granted. It never grants a mode the harness would have refused, and it cannot: it removes capability from the advertised surface and adds none.
The headline guard is uniform across modes — that is what keeps the cached tools prefix byte-stable for the length of a session.
| session can have escalation approved? | advertised enum | description prose |
|---|---|---|
no — approval policy never, no approval service, or unrecognised mode | (fields removed) | escalation paragraph removed |
yes — an approval channel exists and policy is not never | (left exactly as the harness built it) | kept |
The two conditions are session facts, not properties of the current access
level. ApprovalService.decide returns "rejected" outright when the effective
policy is never, before any approver is consulted, so under that policy an
escalation is impossible in every mode — and the right published surface is
also the same in every mode.
An unrecognised mode grants nothing rather than everything: SandboxMode is a
validated closed union, so this cannot arise from a healthy host, and offering an
escalation would be the unsafe guess.
When escalation genuinely can be approved, the guard does not edit the surface
at all. A call that still carries an unusable request is then corrected at
tools/pre-execute, which re-evaluates per call and costs nothing to re-run.
This covers:
ask whose current mode happens to leave nothing wider — for
example danger-full-access, from which no escalation is ever grantable;The correction names the effective mode, states that no value is grantable, and names the repair — unlike the two opaque validations it replaces. See What this plugin does and does not cover for why the enum is not trimmed per mode.
dsh plugin --profile web add github:iimaguest/dsh-sandbox-escalation-guard
That installs from GitHub, writes the dependency, and adds the profile's
bundles entry, so the cordis.patch.yml in this package mounts
automatically. Confirm the row:
grep -A 14 '"bundles"' ~/.dsh/profiles/web/package.json
Activation is a profile load, not a file write. The plugin takes effect when the profile is next loaded.
Verified against dsh 0.2.0-rc.2 (1.0.1) and developed against the 0.1.5-rc.2
line. The plugin declares no @deepseek-ai/dsh-* peer dependencies, so dsh's
startup compatibility gate never inspects it — it mounts on any line by
construction, which is also why nothing warns if a runtime change ever broke it.
Every harness seam it touches was re-checked against the 0.2 runtime: the
system-prompt/assemble and tools/pre-execute events, the
{ kind: 'deny', reason } gate contract, exec.name/exec.arguments, the
approval service's effectivePolicy(session), the sandboxPolicy service's
resolve({ session }).mode, and the sandbox_permissions field name — all
unchanged. The plugin imports nothing from any @deepseek-ai/* package at
runtime (only its own wider-modes.js), reaching every service through lazy
ctx.get() lookups instead, so the 0.1→0.2 package reshuffle cannot break it at
module-link time. npm test (48/48) and tools/verify-modes.mjs run against
the 0.2.0-rc.2 packages installed as devDependencies.
# pull new commits that have landed on GitHub
dsh plugin --profile web update dsh-sandbox-escalation-guard

# remove completely
dsh plugin --profile web remove dsh-sandbox-escalation-guard
To disable it without uninstalling, remove dsh-sandbox-escalation-guard from
the profile's bundles list. To develop against a local checkout instead of
GitHub, dsh plugin --profile web add /path/to/dsh-sandbox-escalation-guard.
- id: dsh-sandbox-escalation-guard
  name: dsh-sandbox-escalation-guard
  config:
    warn: true             # log each intervention to the host console
    resolveMode: ...       # testing seam only; omit in production
    escalationPossible: ... # testing seam only; omit in production
| field | default | meaning |
|---|---|---|
warn | true | Log when the schema is narrowed or a call is corrected. |
resolveMode | (unset) | Overrides effective-mode resolution for the per-call correction. Testing seam; production reads the session's own sandbox/mode fold through sandboxPolicy. |
escalationPossible | (unset) | Overrides whether the published surface keeps the escalation fields. Testing seam; production reads the approval policy. |
This is stated plainly because the coverage changed during development, and the honest version is narrower than an earlier claim in this file.
It covers the case where escalation can never be approved. When the
deployment's approval service exists and the session's policy is never,
ApprovalService.decide returns "rejected" before any approver is consulted,
so an escalation is impossible in every mode. The guard then removes the
escalation fields from the published surface, uniformly, in every mode. This is
the reported configuration (the failing session logged
approval/policy: {policy: never}), and it is fixed.
It also corrects, per call, any unusable request that arrives anyway — a
cached schema, a model ignoring its schema, or a session whose policy is ask.
That check runs at tools/pre-execute, costs nothing to re-evaluate, and names
the exact repair.
It does NOT narrow the advertised enum to the values grantable from the current mode. An earlier revision did, and that was wrong twice over:
It broke the cache. The enum moved whenever the access level changed, and the tools block is the front of the cached prefix, so a mode switch discarded the entire cached conversation behind it.
It published a value that was going to be rejected anyway. A
workspace-write session advertised ["danger-full-access"]. Omitting a
field is always safe; publishing a value that is later rejected is what breaks
a model. The set that is safe in every mode a session can be switched into
is the intersection across those modes — and it is empty as soon as the
range includes danger-full-access:
| mode | grantable from it |
|---|---|
read-only | workspace-write, danger-full-access |
workspace-write | danger-full-access |
danger-full-access | (none) |
No value is grantable from all three, so a surface that never offers a rejected value cannot offer any value.
The one residual, stated plainly. The remaining gap needs a composition no
shipped preset produces: an approval policy of ask paired with
danger-full-access. There the fields survive (the policy says an escalation
could be approved) while the mode says no value is wider, so a GPT-family model
can still fill them and collect one rejected call — corrected by the
tools/pre-execute listener rather than prevented. That listener names the
effective mode and the exact repair, so the failure is a clear correction rather
than the opaque loop that motivated this plugin.
If you build such a composition and want the tighter surface, set
escalationPossible: false to suppress uniformly. That is a statement about your
deployment, made by your deployment — not a guess this plugin makes from a mode
it cannot know is stable.
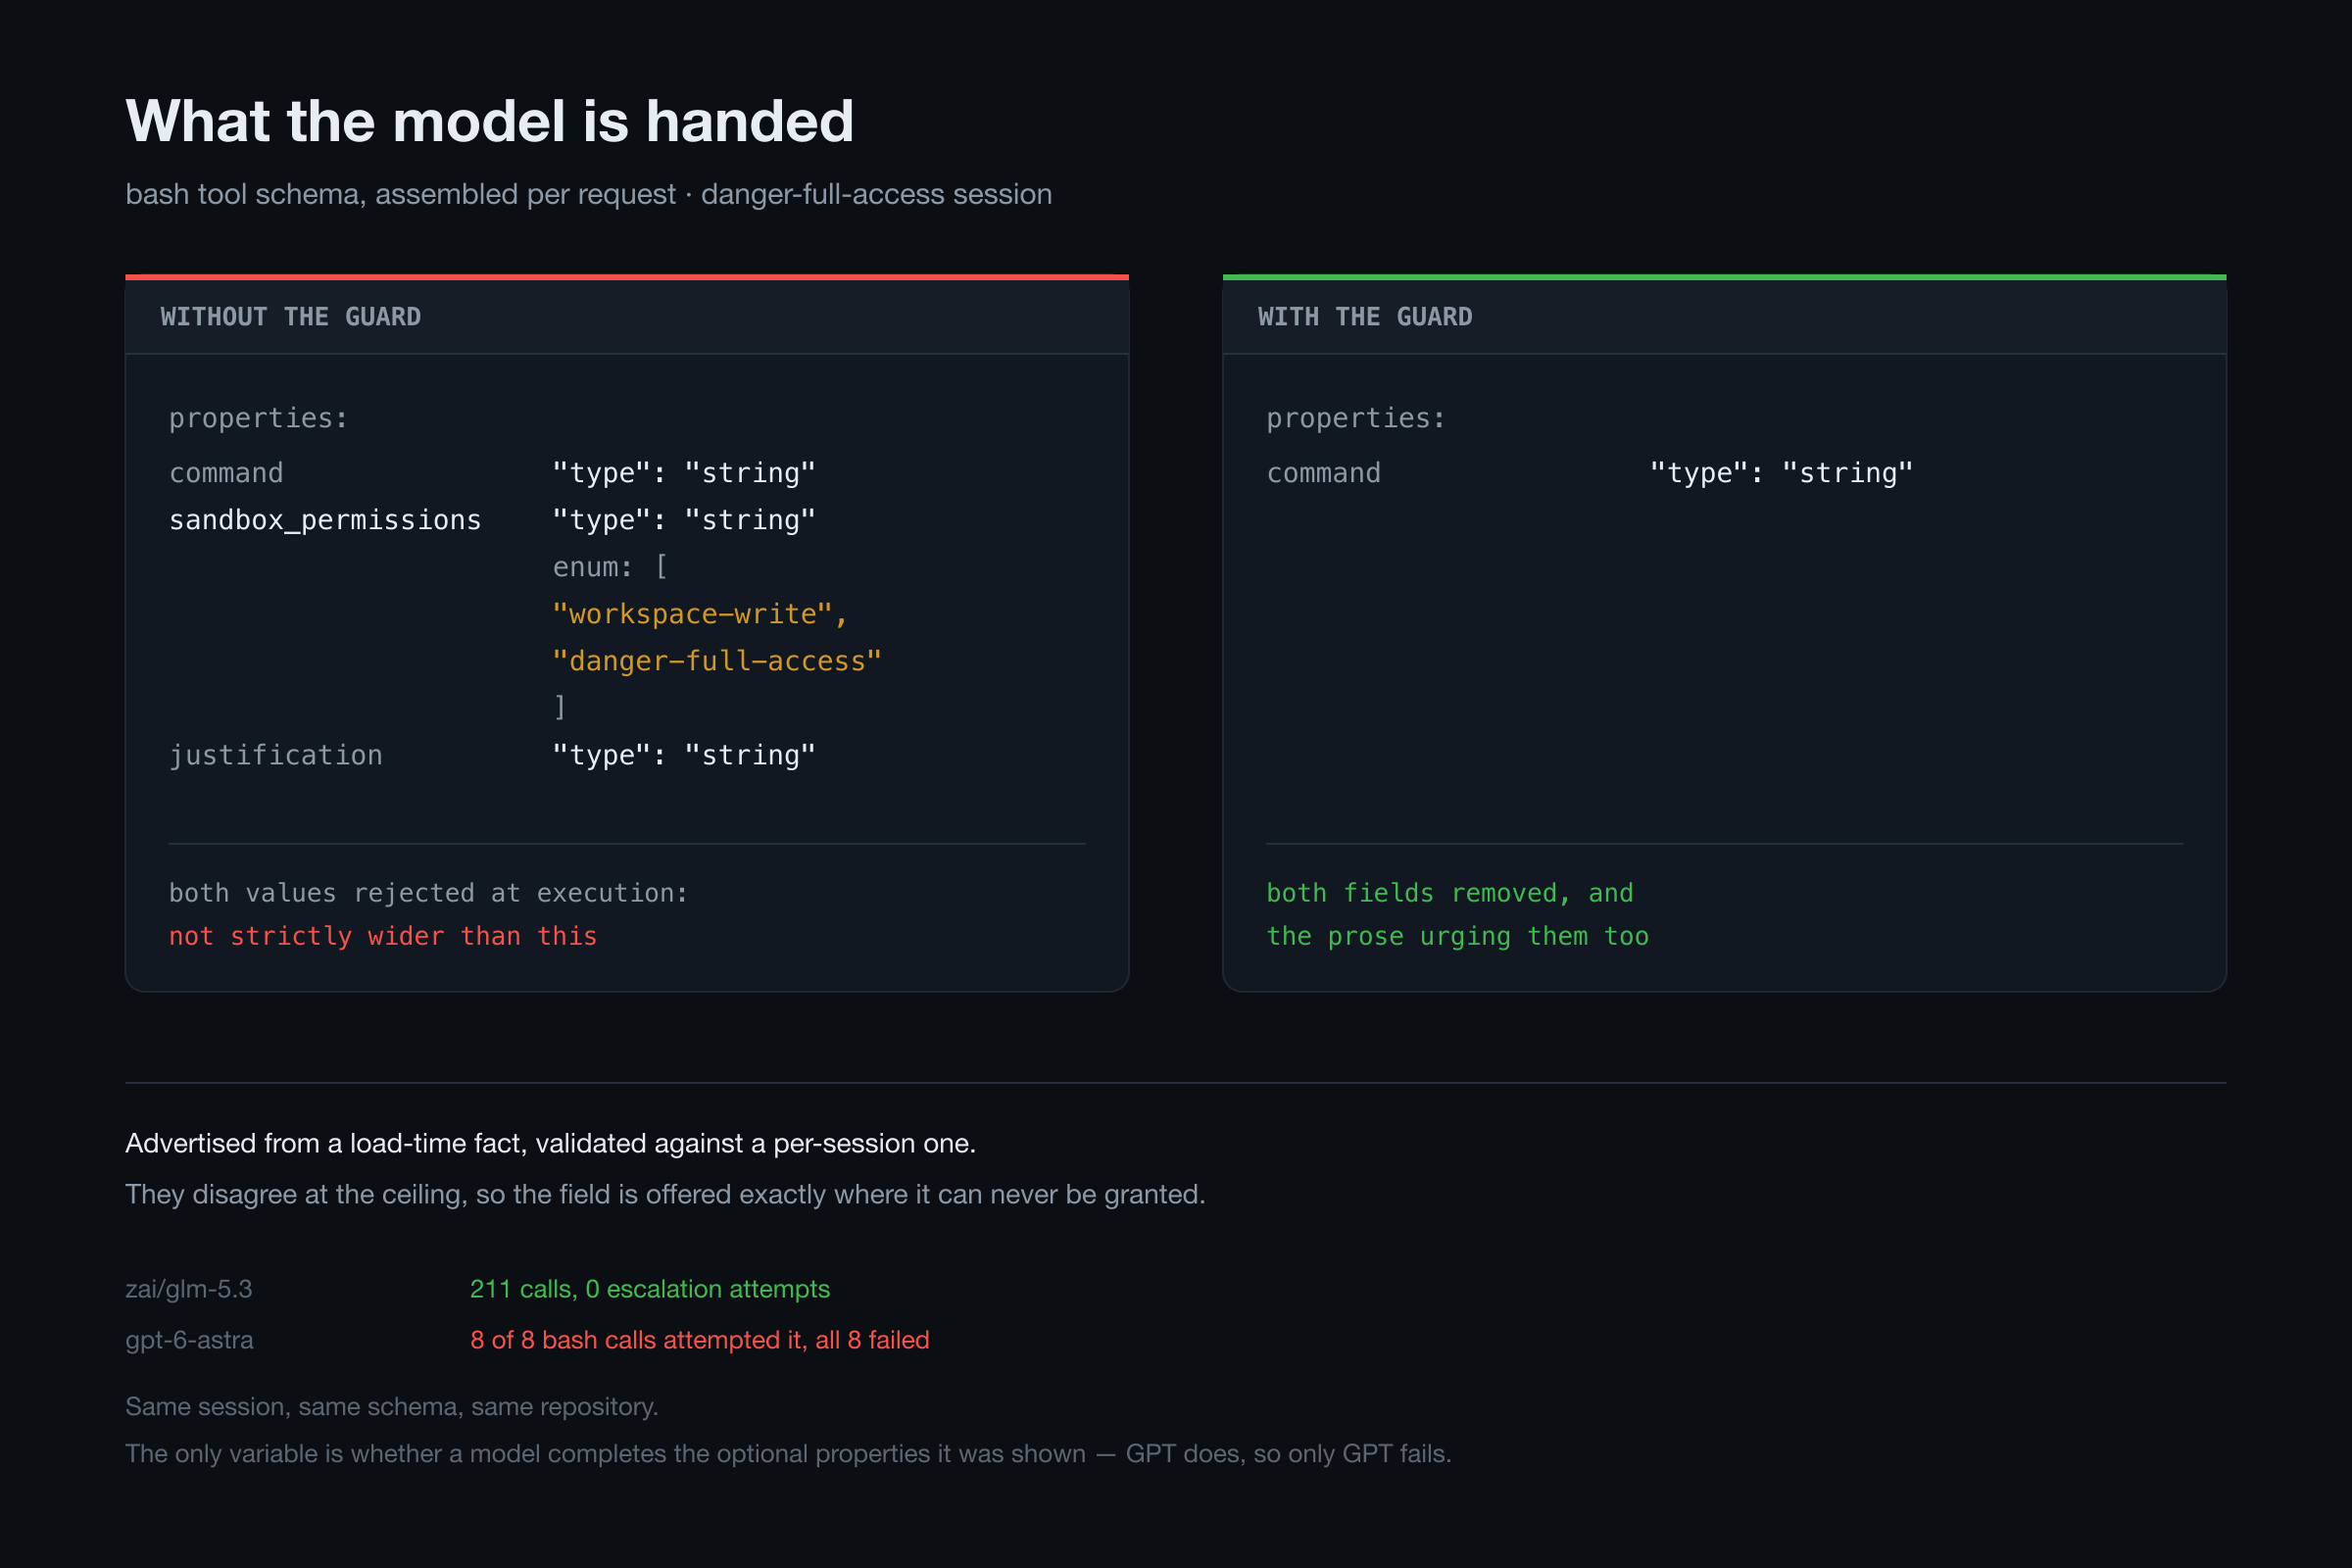
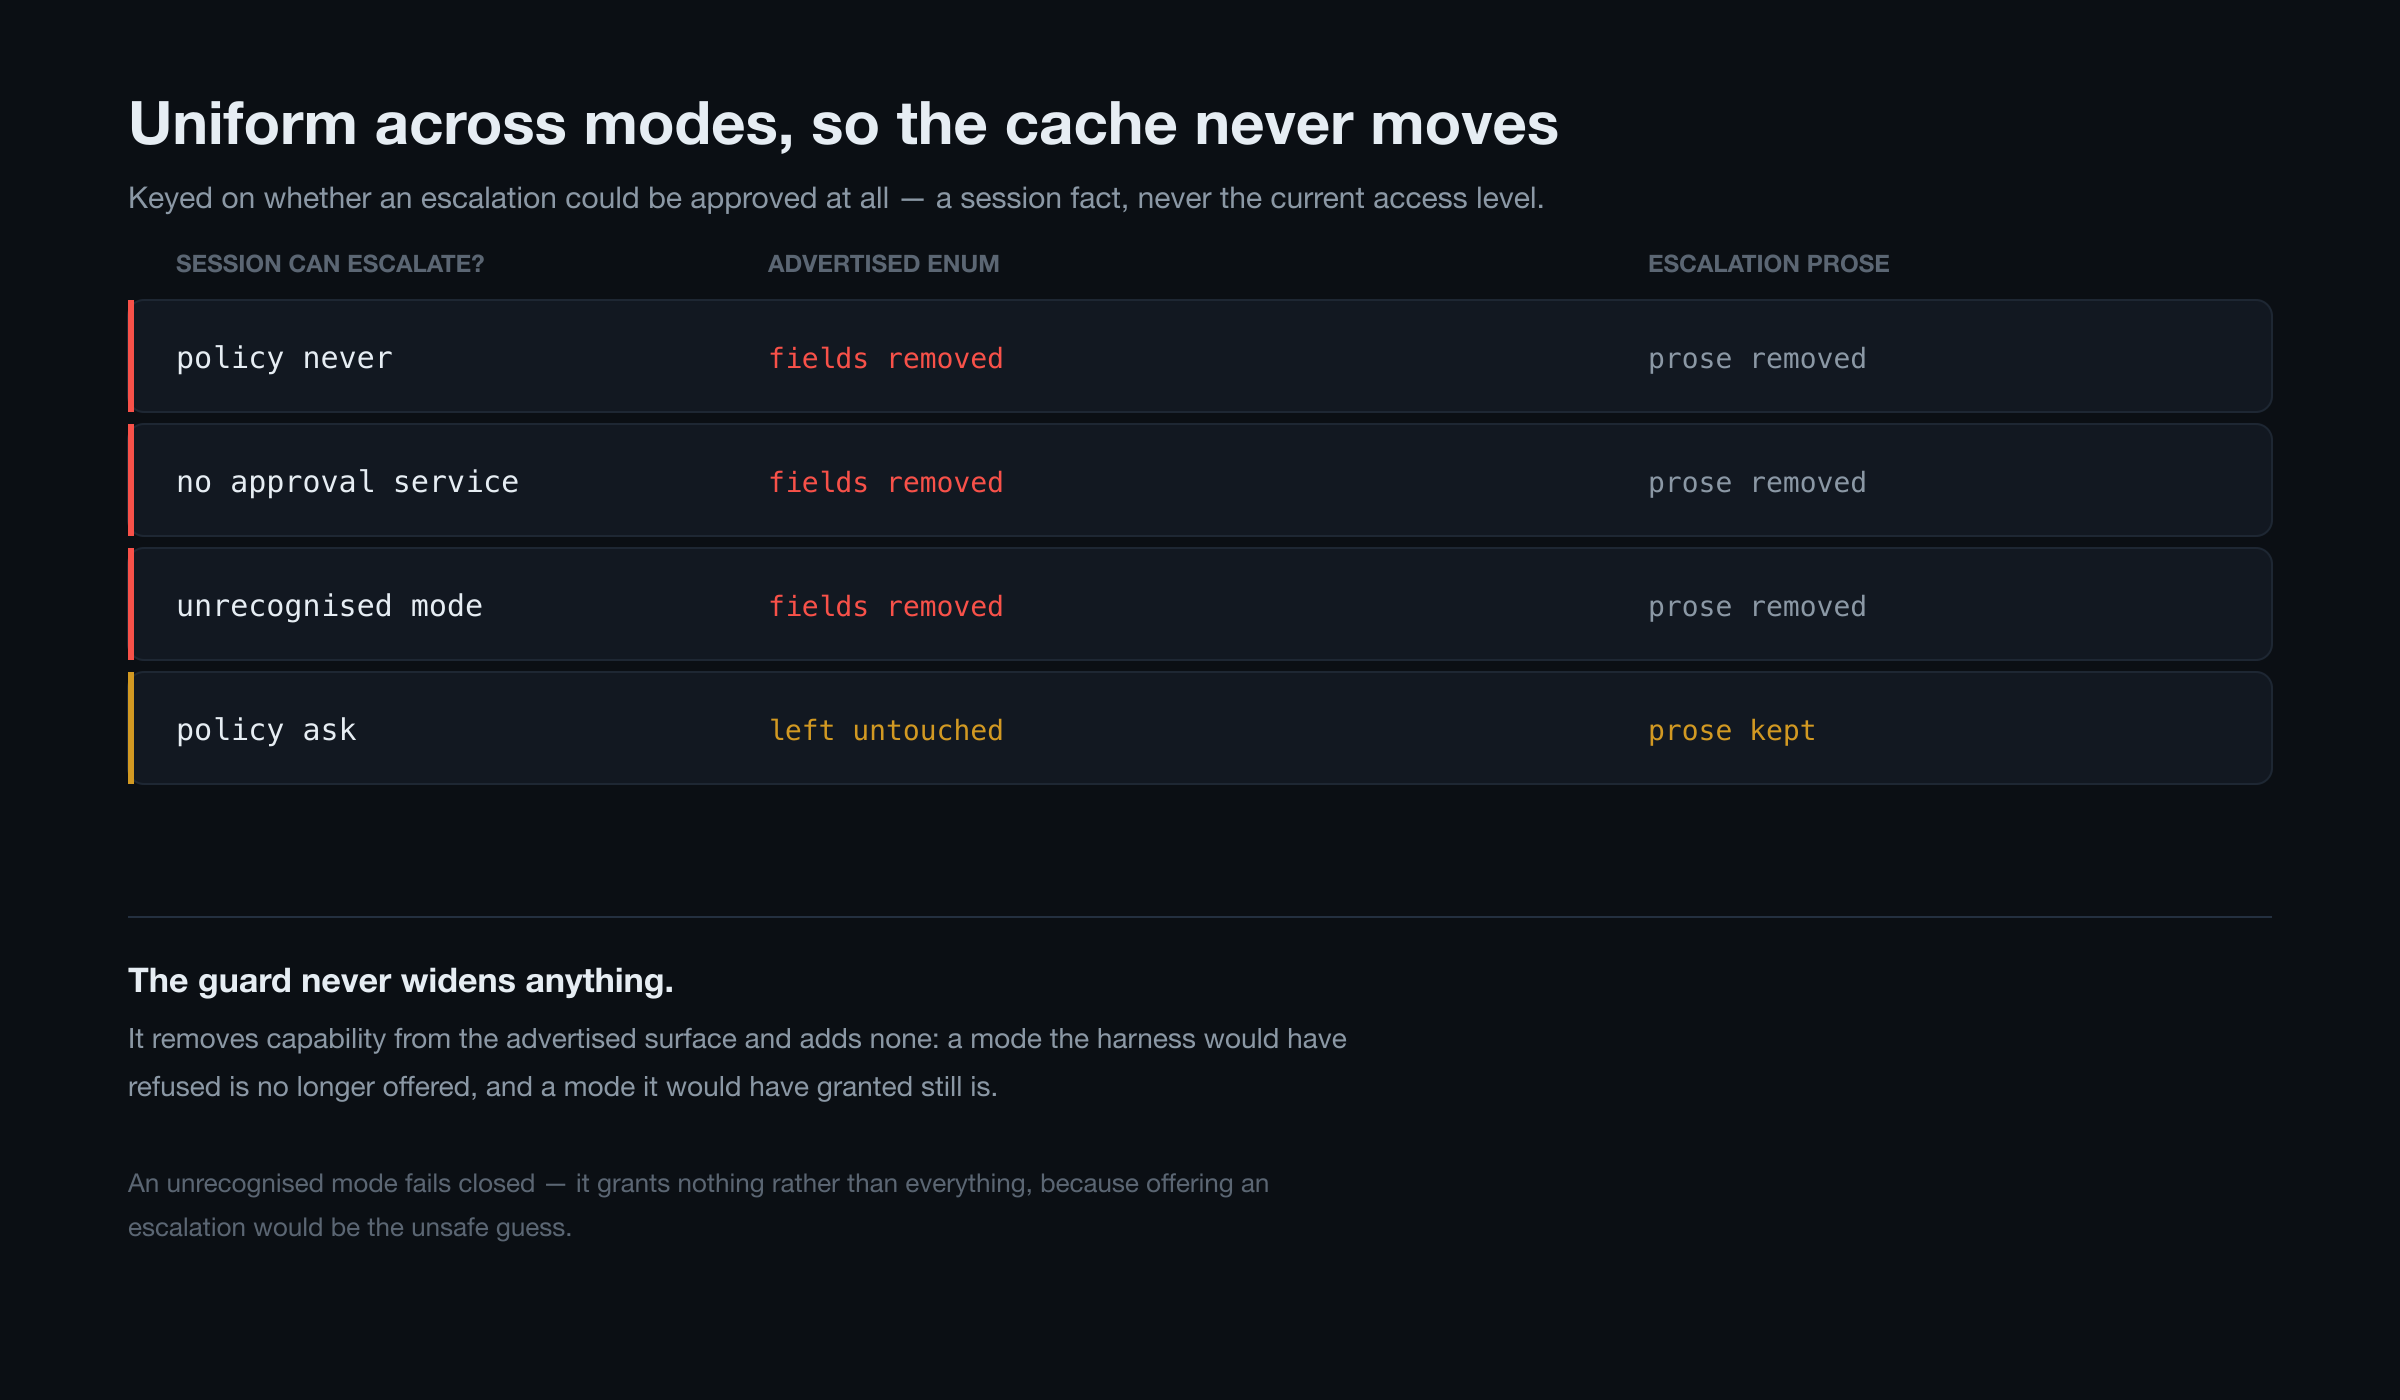
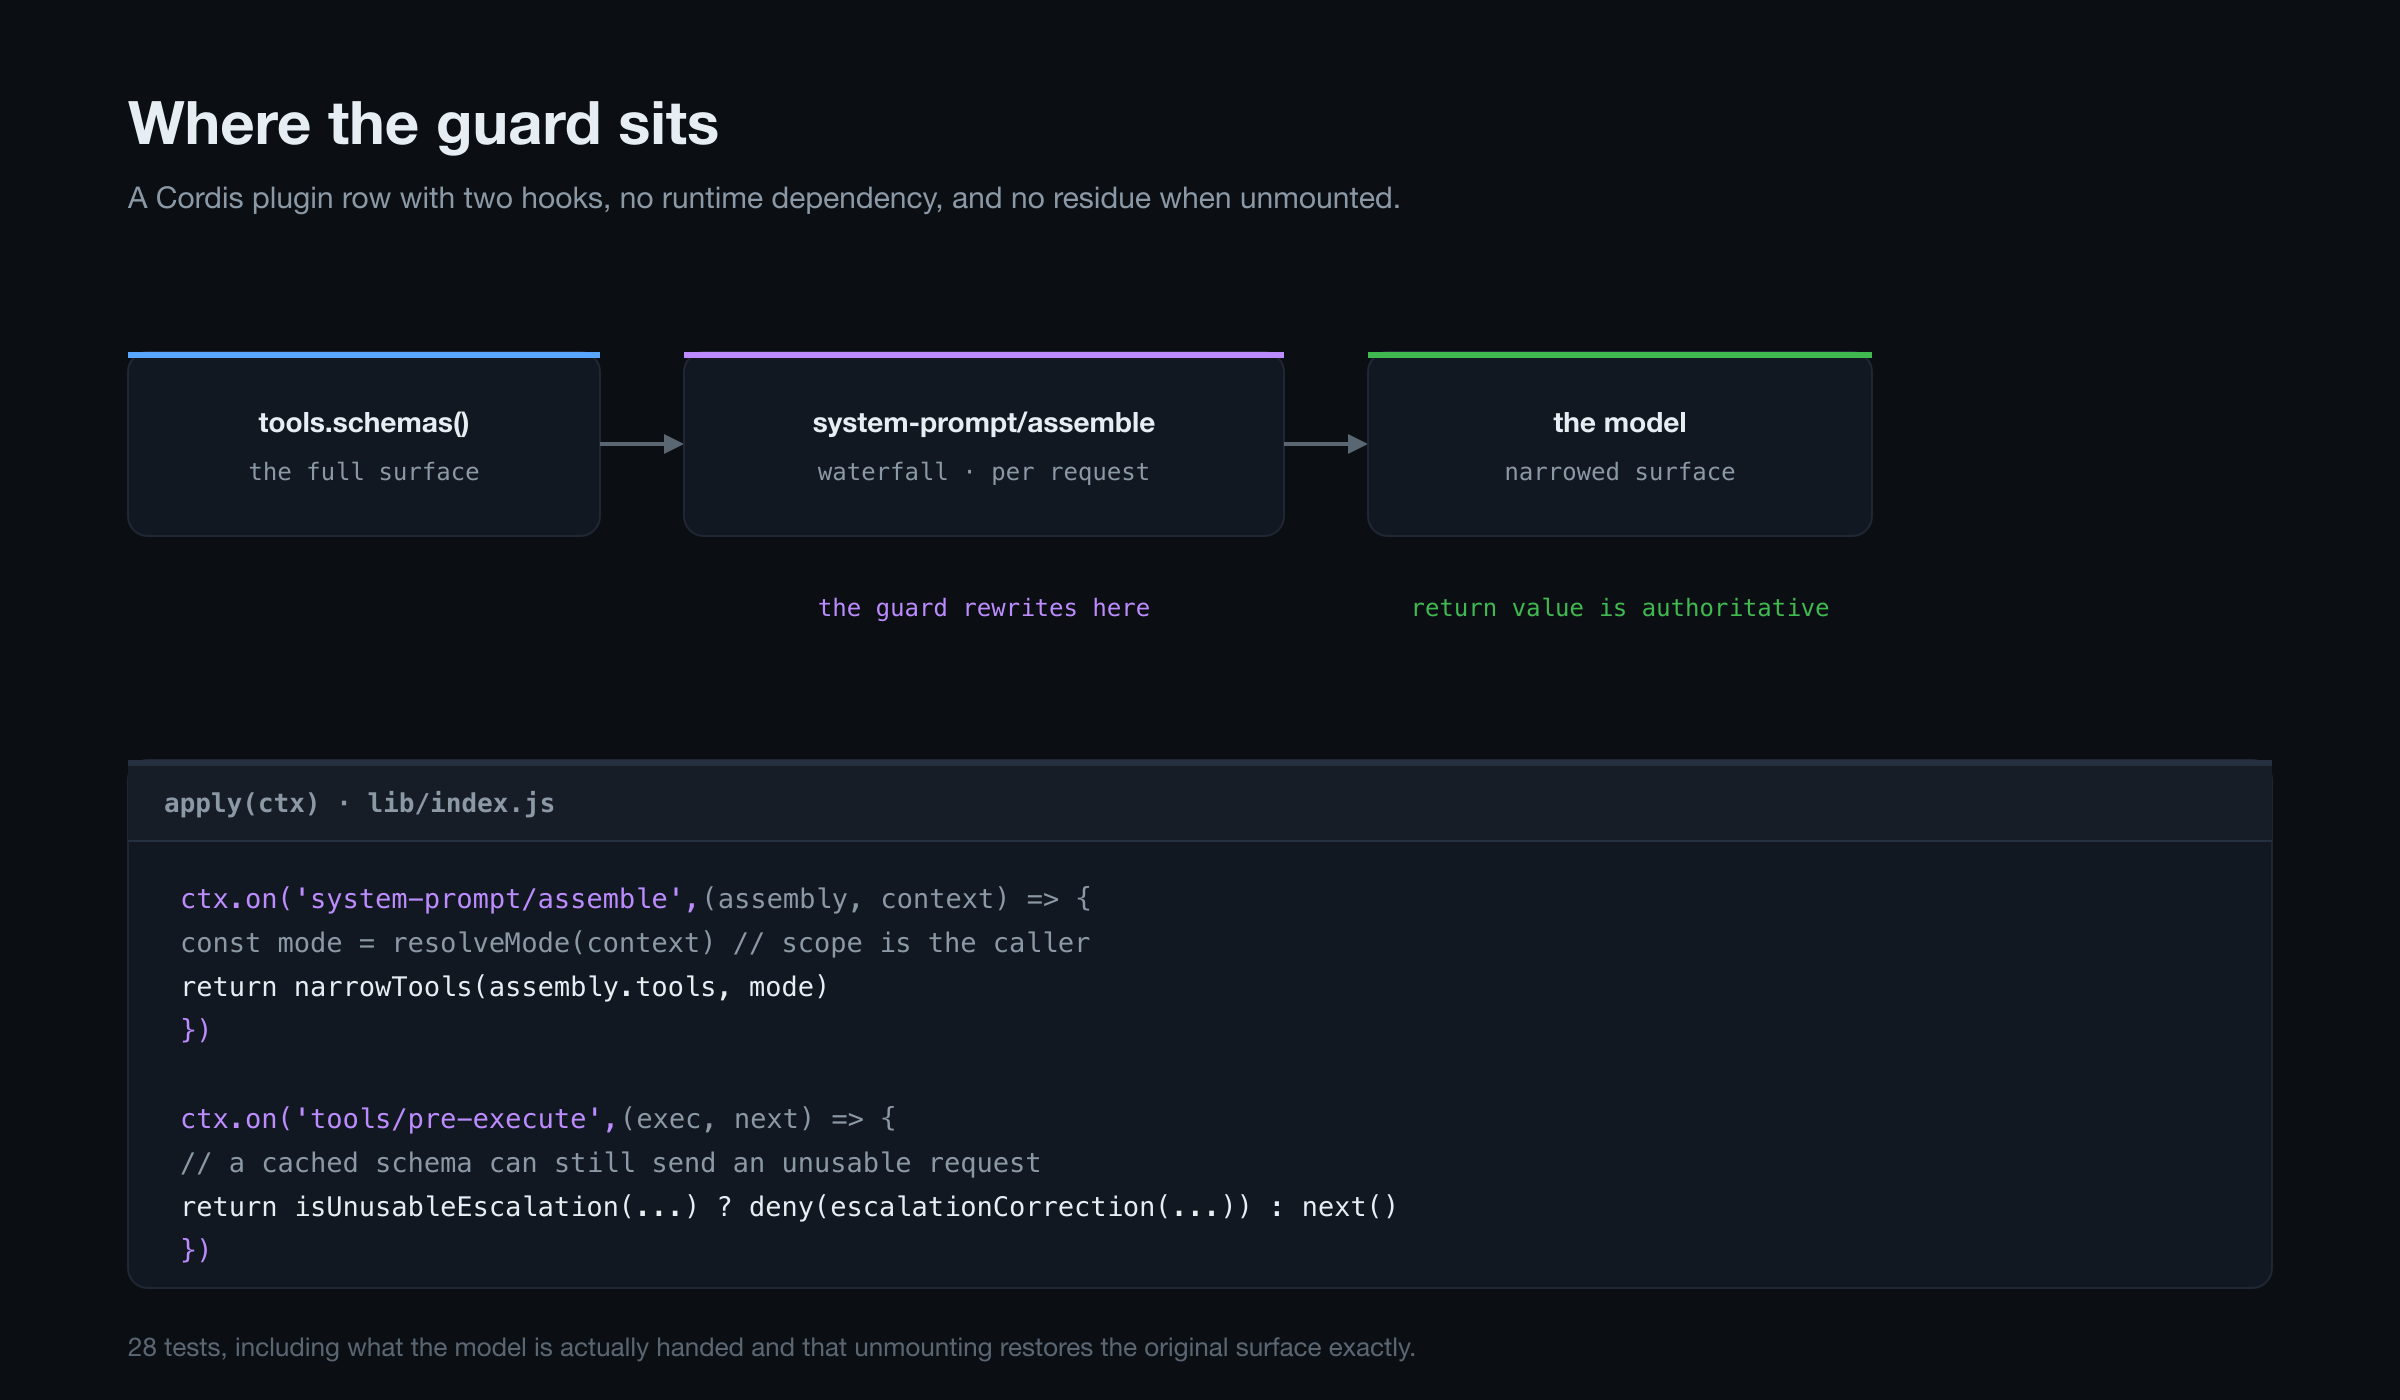
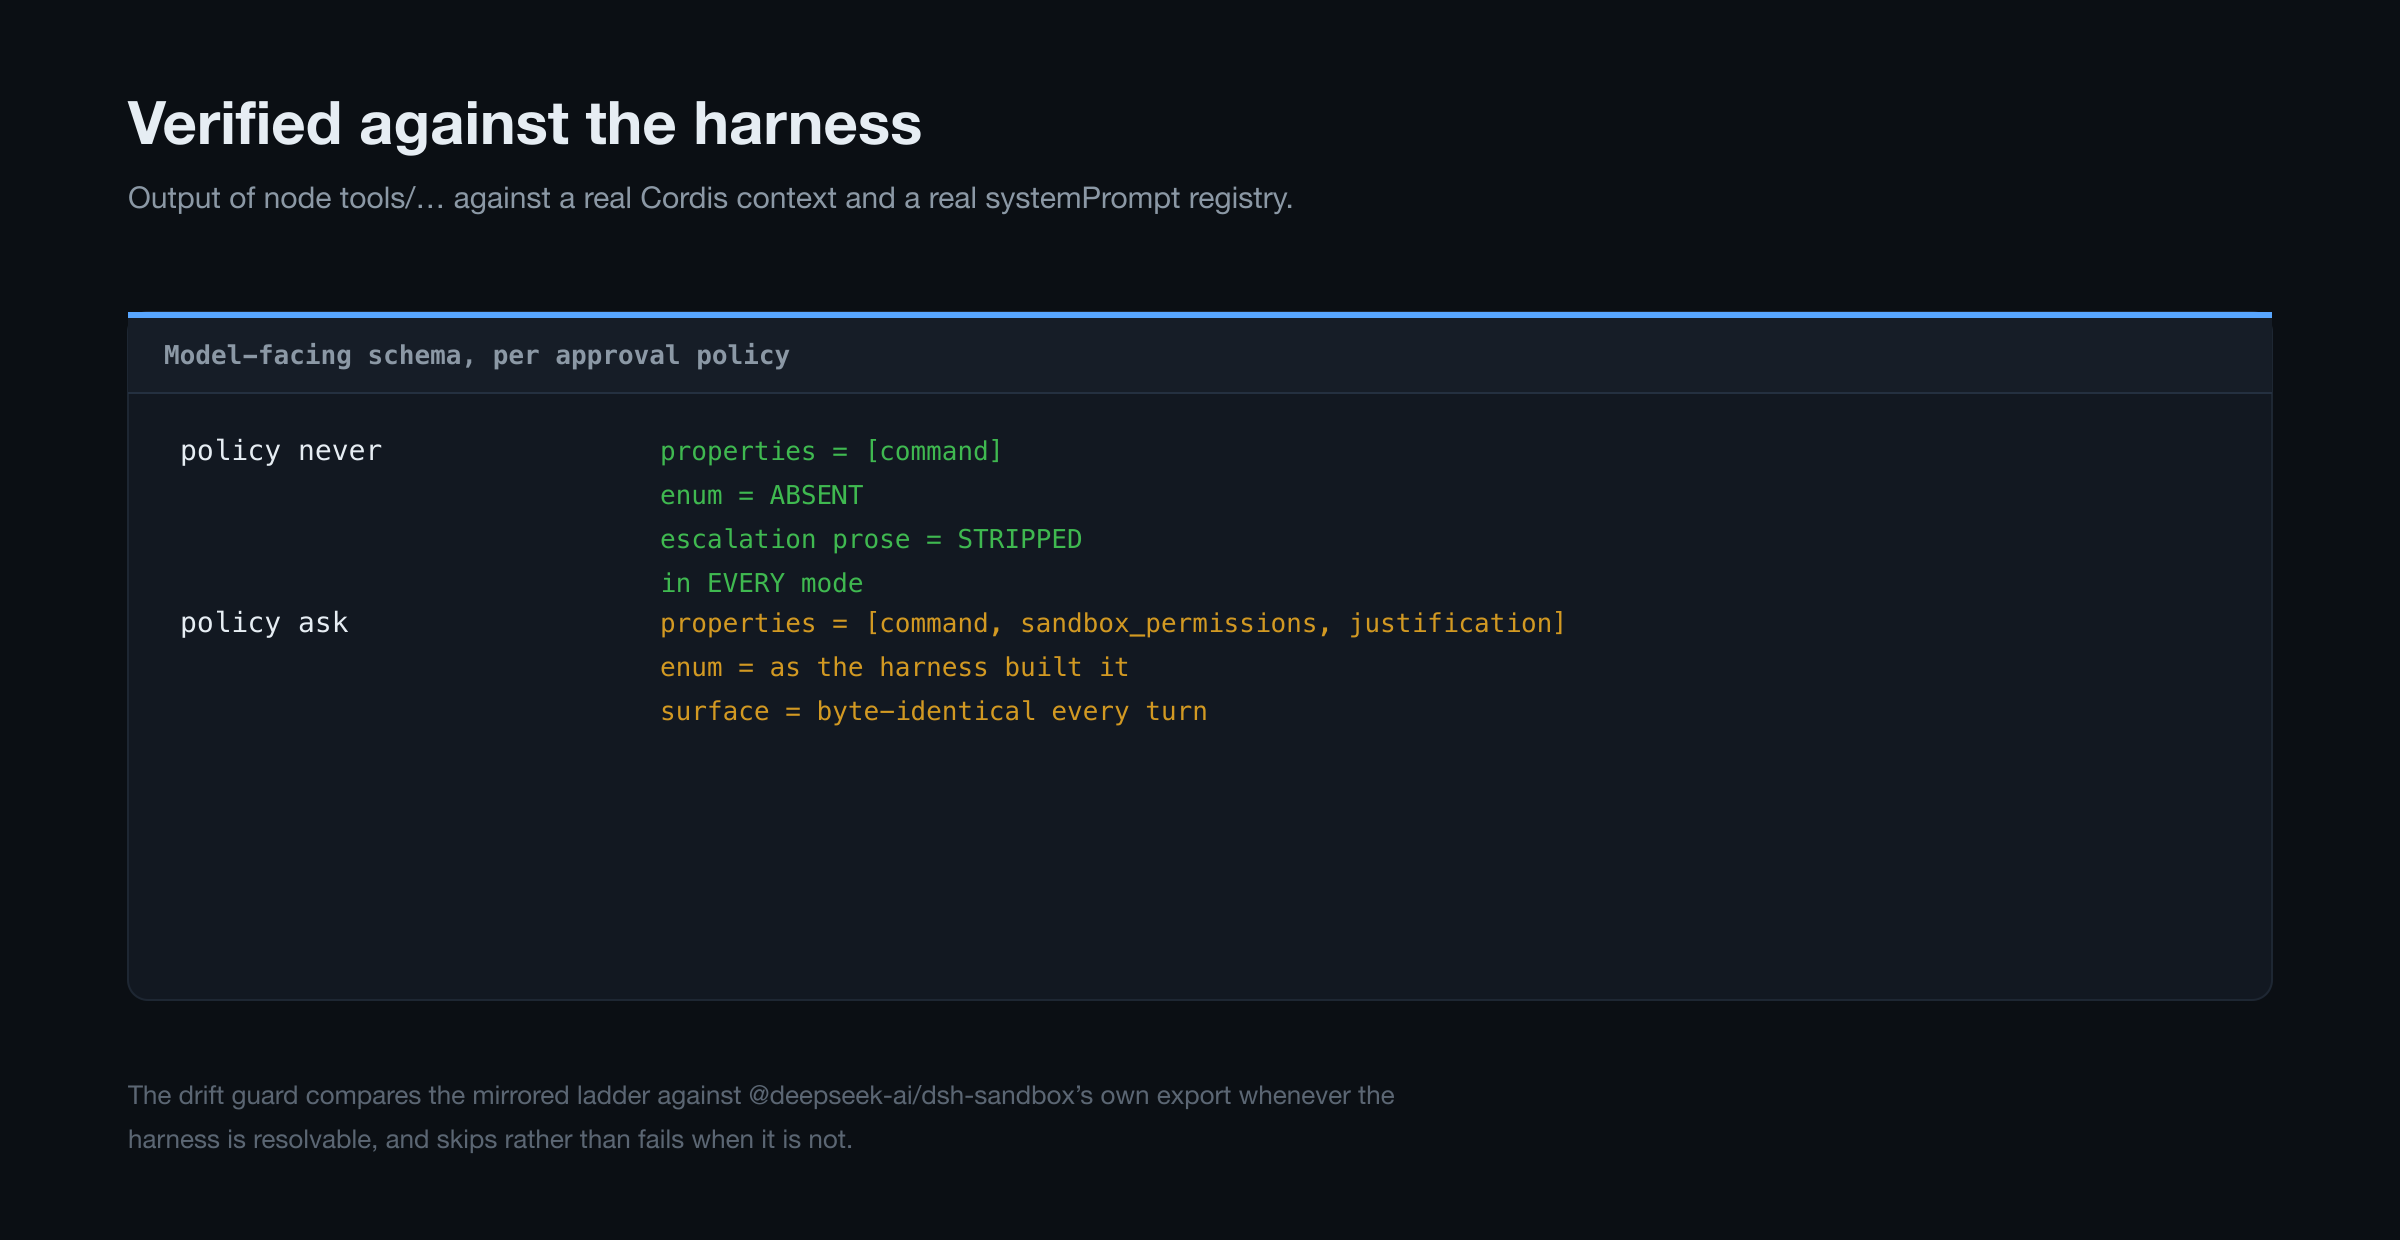
These are diagrams of the harness's own contracts rather than captures of a UI,
and every value in them is copied from verified output — generating them is
npm run screenshots, and the mode table in the last image is exactly what
npm run verify prints.
npm install
npm run verify
Mounts the plugin against a real Cordis context and a real systemPrompt
registry and prints the model-facing bash schema for each session mode — the
plugin's observable claim, reproducible rather than described.
npm test
48 tests:
test/guard.test.mjs — the suppression matrix, the strictly-wider table
against approveEscalation's judgement, and prose stripping.test/wider-modes.test.mjs — drift guard: the mirrored ladder is compared
against @deepseek-ai/dsh-sandbox's own export whenever the harness is
resolvable, and skipped (not failed) when it is not.test/mount.test.mjs — the plugin applied to a real Cordis context and a
real systemPrompt registry, asserting what the model would be handed, that a
session which can escalate keeps the harness's own bytes untouched, that the
published surface does not move when the access level changes, that
unmounting restores the original surface exactly (so this is an ordinary plugin
row with no residue), and that the pre-execute correction fires only on
unusable requests. Some of these mount the plugin before the policy service
exists and then provide it, which is the real boot order — see the note below.
Others mount neighbouring listeners on both sides of the guard, and
re-assemble fifty times per mode to prove the output bytes never move.test/real-services.test.mjs — the same contract mounted against the
harness's real ApprovalService and SandboxPolicy, not the testing seam.
This is the file that proves the gate reads the harness's own approval fact:
a fake { effectivePolicy: () => 'never' } agrees with any implementation,
including a wrong one. Skipped (not failed) when the harness is unresolvable.ctx.waterfall dispatches through a chained thunk — (cbs.shift() ?? inner) —
so a listener that returns without calling next() ends the chain for every
listener registered after it. The first version of this plugin did exactly that,
which silently suppressed the system-prompt/assemble listeners of
dsh-session-reference and dsh-agent for the whole process. Their
contributions never reached a request and nothing reported the loss; it was
found by probing the dispatcher against two listeners, not by any single-listener
test. The listener now awaits next() and narrows the result, which is also
the correct order — the model must receive the final assembly.
ctx.get('sandboxPolicy') must not be read once inside apply and closed over.
A bundle patch is appended to the composition, while sandbox-policy sits
earlier in the base tree and is provided asynchronously, so the row can load
before the service exists. Closing over the result binds undefined and the
plugin then narrows nothing for the entire session — silently, having printed a
warning that looks like a missing dependency rather than a race.
Declaring sandboxPolicy in inject is the other wrong answer: it defers
apply until the service appears, so on a composition that genuinely lacks it
the plugin waits out the session with no hooks registered and no diagnostic at
all. The guard resolves the service per request instead, mounts unconditionally,
and reports a genuinely absent service once, at the first request it cannot
serve. mount.test.mjs pins both halves: untouched before the service arrives,
narrowing immediately after.
The escalation-prose fixtures in guard.test.mjs are copied verbatim from the
shipped dsh-tool-bash and dsh-tool-fs descriptions. If a DSH upgrade reworks
that wording, the prose tests fail loudly rather than this package silently
ceasing to strip prose.
It cannot repair the schema's origin. This plugin rewrites the schema on its
way to the model; it does not change dsh-tool-bash or dsh-tool-fs. The
underlying predicate — advertising from ctx.shell.sandboxMode while validating
against ctx.sandboxPolicy.resolve() — remains the harness's own, and the
correct upstream fix is to gate the fields on the session's resolved mode (and
to accept the current mode as a no-op). This plugin is the durable workaround
for an install that must not patch node_modules.
Prose stripping is anchored, not structural. The escalation paragraph is removed by matching its leading clause. If a future DSH rewrites that text the schema fix still applies and only the prose is left behind — the model keeps its instructions but loses the fields they refer to. The pinned tests make that visible.
The pre-execute fallback denies rather than executes. Letting the call
proceed by stripping the arguments would require re-implementing tool
dispatching, because exec.arguments is deep-frozen before any plugin
observes it. A denial that names the repair is the safe choice; with (1) active
it should never fire.
A listener registered after this one can still re-add the fields. The
guard narrows the assembly returned by next(), which carries the work of every
listener upstream of it in the chain. A plugin that appends tool schemas and
happens to register after this one would put un-narrowable fields back.
Middleware order is absolute and cannot be corrected from inside the waterfall.
This does not arise with the shipped set: dsh-session-reference and
dsh-agent both call next() and only read assembly.variables, adding no
tools.
The guard rewrites request content, which is the exact shape of change that can quietly destroy a provider's prefix cache. So this is measured against what the providers actually document, not assumed.
| Provider | Rule |
|---|---|
| OpenAI | Changing tools changes "names, descriptions, schemas, ordering, or tool-specific instructions". Cache reuse "requires the entire rendered prefix to match". |
DeepSeek Harness(DSH)Web 插件聚合生态包 · 一切皆插件,创意工坊分发(dsh-market.com)
把回答做成一页可视化 HTML:模型只写简短的 Markdown 草稿,随包附带的 `am` 命令行生成页面,支持流程图、时序图、树、时间线、ER 图、表格和提示框。
在 dsh 里装上这个插件即可,无需登录、注册或填 API Key,就能使用包括 Muse Spark 1.3、MiMo V2.6 在内的前沿模型——完全免费,不限量。 All you do is install this plugin in dsh: no login, no sign-up, no API key — the frontier models are just there, Muse Spark 1.3 and MiMo V2.6 among them. Completely free, with no usage cap.

